Python 多进程、多线程、异步编程与GPU加速
知止自律打卡-微信小程序APP
一款微信自律打卡小程序,支持自定义打卡项目、习惯记录、项目日记、专注计时与数据统计。自律打卡、学习打卡、读书打卡、健身打卡、运动打卡、减肥打卡、戒色打卡、养生打卡、戒烟、戒酒、戒熬夜等多种场景。万能打卡模板自由创建。可自定义每日打卡目标,记录习惯连续天数,可视化追踪成长进度。
了解产品详情 →
微信搜索「知止自律打卡」
前言
多进程:适合CPU密集型任务。
多线程:适合I/O密集型任务,能欧提高并发性。
异步编程:适合I/O密集型任务,通过事件循环实现任务的并发执行。
GPU加速:大规模计算、深度学习。
1 多进程
多进程(Multiprocessing)是实现并行的一种常见方式。
每个进程有自己的独立内存空间。
from multiprocessing import Pool
import math

# 计算阶乘
def compute_factorial(n):
    return math.factorial(n)

if __name__ == "__main__":
    numbers = [3, 5, 10]
    # 创建进程,最大2个任务并行处理
    with Pool(processes=2) as pool:
        # pool.map:分配任务
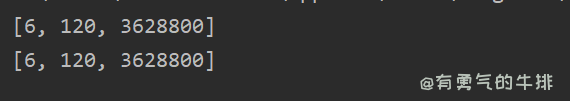
        results = pool.map(compute_factorial, numbers)
        print(results)

    print(results)
    # 输出:[6, 120, 3628800]
2 多线程
多线程(Multithreading)。
-
一个进程可以创建多个线程。
-
Python有GIL(全局解释器锁)会限制,即同时只能有一个线程执行。
在I/O密集型任务重,多线程仍然可以提高程序并发性。
import threading
import time

def print_thread_info(thread_name, delay):
    """线程执行的函数"""
    print(f"线程 {thread_name} 开始")
    time.sleep(delay)
    print(f"线程 {thread_name} 结束,延迟 {delay} 秒")

if __name__ == "__main__":
    # 创建多个线程
    thread1 = threading.Thread(target=print_thread_info, args=("线程1", 2))
    thread2 = threading.Thread(target=print_thread_info, args=("线程2", 3))
    thread3 = threading.Thread(target=print_thread_info, args=("线程3", 1))

    # 启动线程
    thread1.start()
    thread2.start()
    thread3.start()

    # 等待线程完成
    thread1.join()
    thread2.join()
    thread3.join()

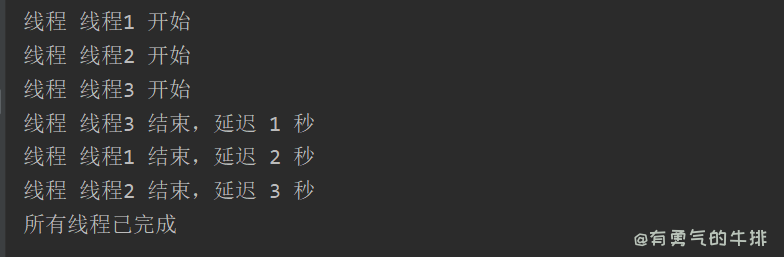
    print("所有线程已完成")
3 异步编程
异步异步编程 :Asynchronous Programming
-
通过事件循环实现任务的并发执行。
-
不是传统意义上的并行(不使用多个CPU核心),允许在等待I/O执行时,执行其他任务。
import asyncio

async def fetch_data():
    await asyncio.sleep(1)  # 模拟 I/O 操作
    return "data"

async def main():
    tasks = [fetch_data() for _ in range(5)]
    results = await asyncio.gather(*tasks)
    print(results)
    # 输出:['data', 'data', 'data', 'data', 'data']

if __name__ == "__main__":
    asyncio.run(main())
4 GPU 加速
场景:深度学习、科学计算
import torch

def compute_on_gpu():
    device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
    x = torch.rand(10000, 10000, device=device)
    y = torch.rand(10000, 10000, device=device)
    z = torch.matmul(x, y)
    return z

if __name__ == "__main__":
    result = compute_on_gpu()
    print(result)
标签: